
WACV 2026
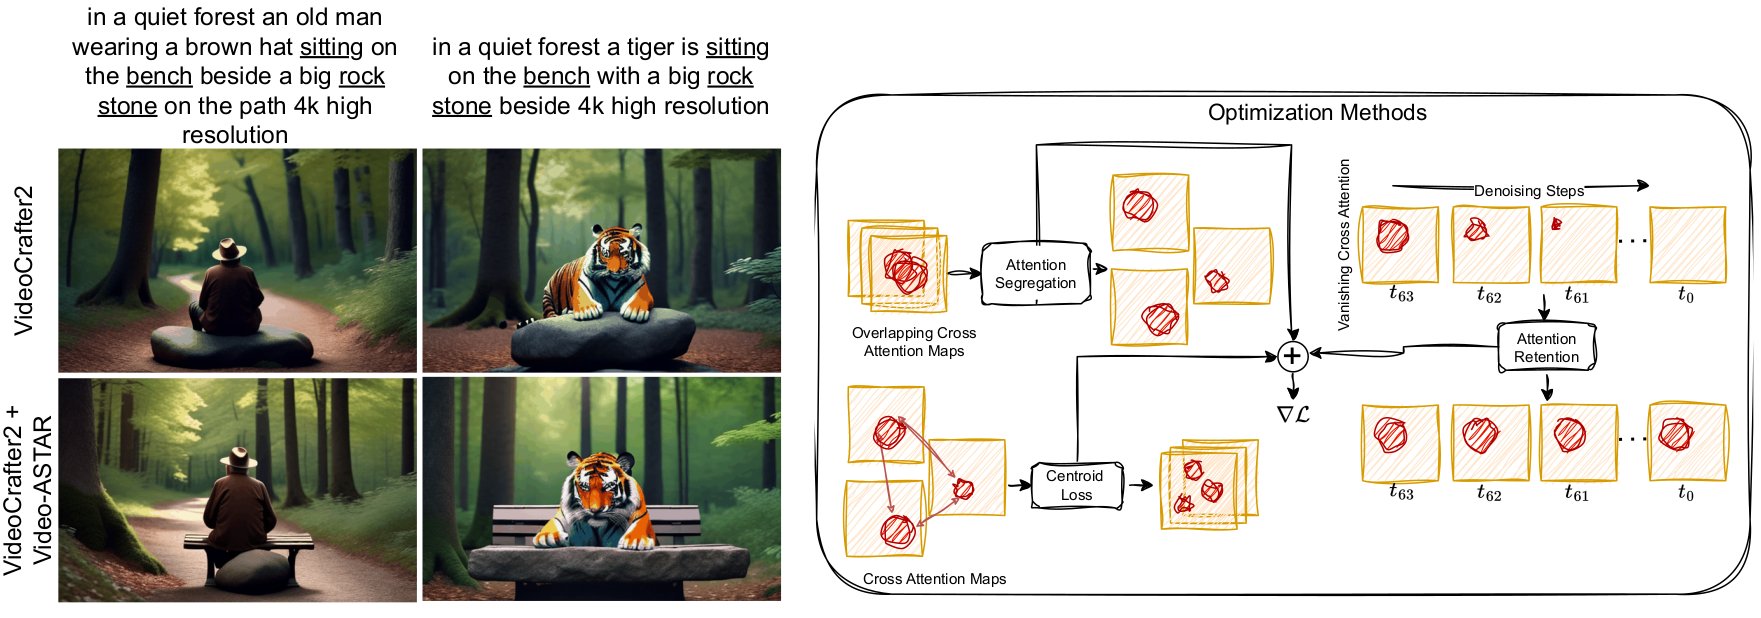
Synthesizing Compositional Videos from Text Description
Composes multi-object videos from a text prompt with no training, on a frozen video diffusion model.
Generative Vision · 3D Modeling · Brain Decoding
Building generative models that capture, reconstruct and interpret the visual world, from video and 3D scenes to brain signals.
Postdoctoral Fellow, Computer Vision, Imaging & Graphics (CVIG) Lab · IIT Gandhinagar
I completed my PhD in Computer Science and Engineering at IIT Gandhinagar under the guidance of Prof. Shanmuganathan Raman, supported by the Prime Minister's Research Fellowship in May 2026.
Training-free and test-time optimization methods that keep frozen diffusion models consistent, for camera-controlled multi-view synthesis and compositional video generation.
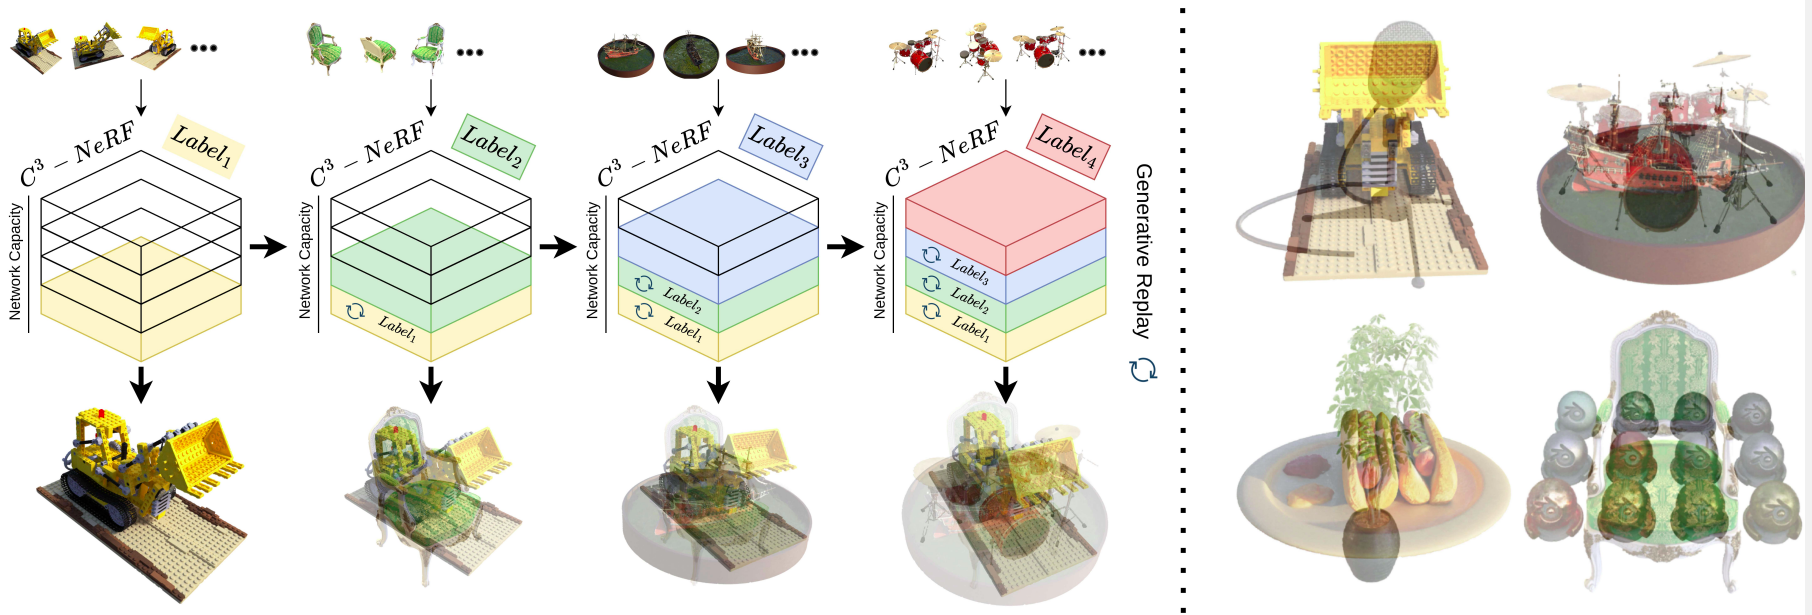
Neural graphics primitives that learn many scenes one after another inside a single model, without catastrophic forgetting.
Generative architectures that reconstruct still and moving visual stimuli from EEG, with a focus on latent space alignment and semantic analysis.
I am also interested in representation learning, graph neural networks, multimodal learning, neural rendering and brain-computer interfaces.
A few papers that show where my work is headed.
WACV 2026
Composes multi-object videos from a text prompt with no training, on a frozen video diffusion model.
Preprint 2025
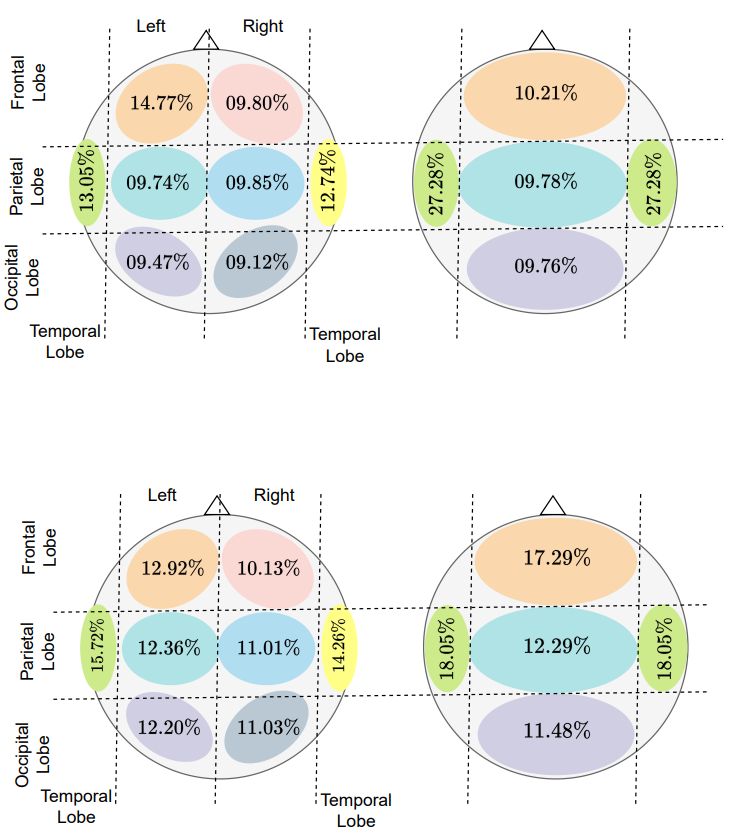
Asks what EEG-to-video decoding actually recovers of visual experience.
BMVC 2025
Learns many 3D scenes in a single NeRF without forgetting the earlier ones.

BMVC 2026
Explains why mixing several sound sources breaks image generation, and fixes it.
WACV 2024
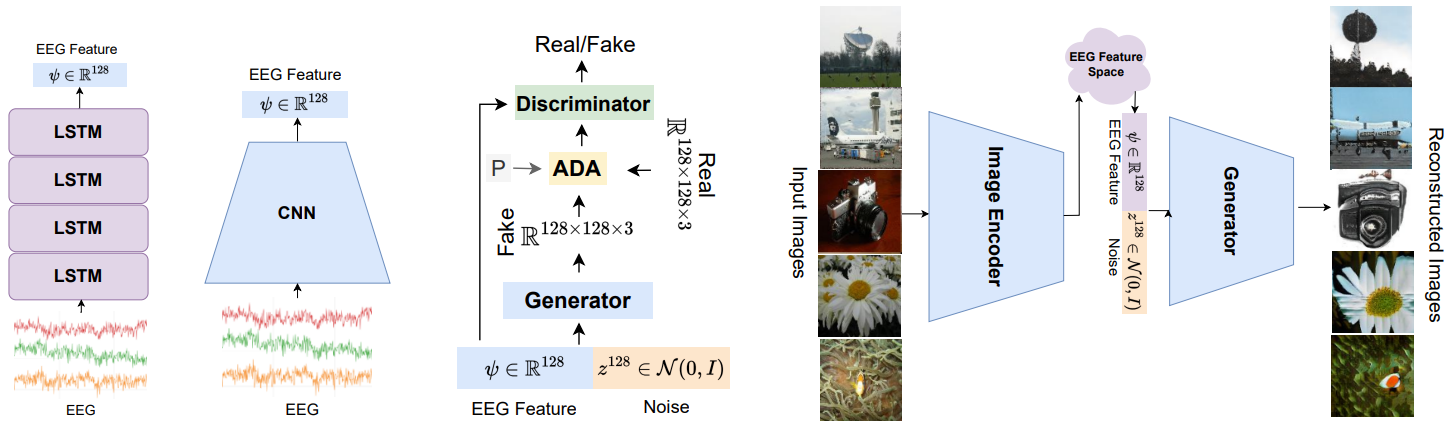
Learns robust visual representations from EEG. Featured in WACV Daily and Best of WACV 2024.
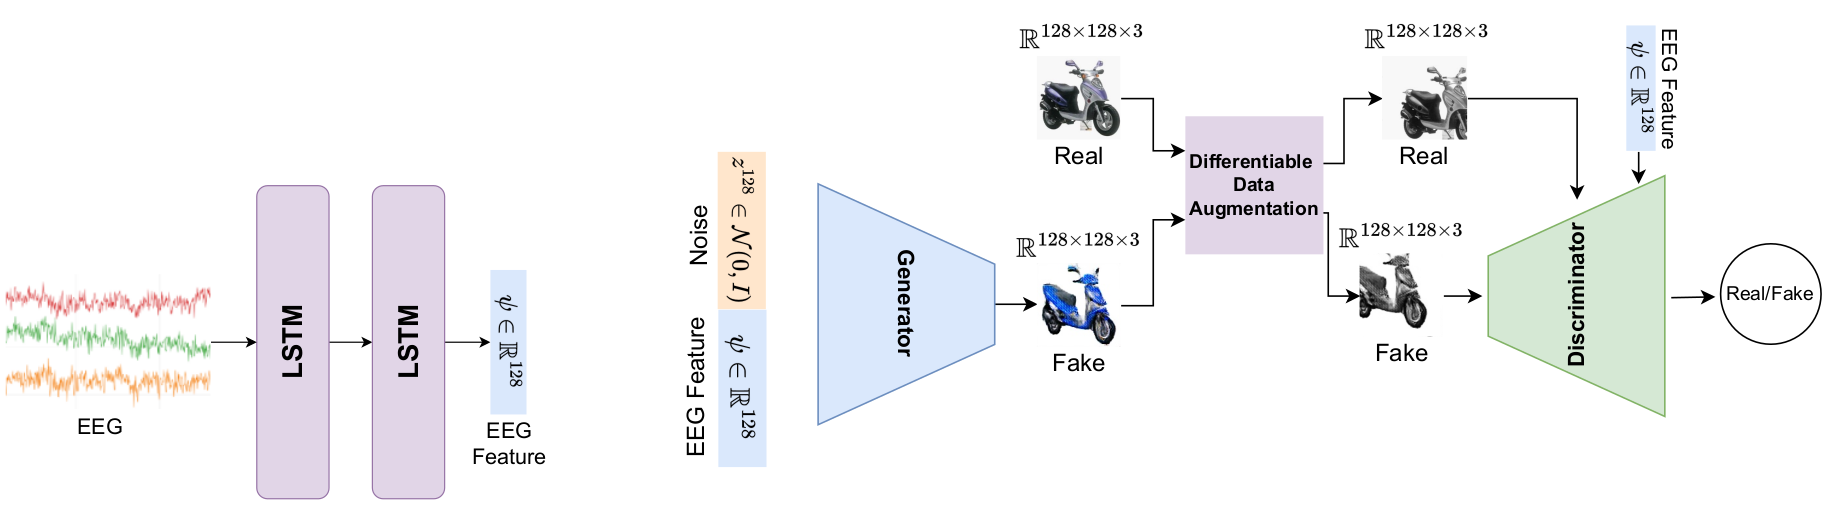
ICASSP 2023
Reconstructs images from EEG signals with contrastive learning and a conditional GAN.