Research over time
Hover over a year, or tap it on a phone, to see the work from that year.
- 2022
- 2023
- 2024
- 2025
- 2026
20223 works
20235 works
- LDR to HDRGenerative visionSingle Image LDR to HDR Conversion using Conditional Diffusion. ICIP 2023
- Hand Shadow Art3D and graphicsHand Shadow Art: A Differentiable Rendering Perspective. Pacific Graphics 2023, Poster
- Mesh blending3D and graphicsA Graph Neural Network Approach for Temporal Mesh Blending and Correspondence. arXiv 2023
- TreeGCN-ED3D and graphicsTreeGCN-ED: Encoding Point Cloud using a Tree-Structured Graph Network. Pacific Graphics 2023, Poster
- EEG2IMAGEEEG and brain decodingEEG2IMAGE: Image Reconstruction from EEG Brain Signals. ICASSP 2023
20242 works
- Knot rendering3D and graphicsSearch Me Knot, Render Me Knot: Embedding Search and Differentiable Rendering of Knots in 3D. Computer Graphics Forum 2024
- EEG representationsEEG and brain decodingLearning Robust Deep Visual Representations from EEG Brain Recordings. WACV 2024
20253 works
- C-NGP3D and graphicsIncremental Multi-Scene Modeling via Continual Neural Graphics Primitives. BMVC 2025
- EEGVidEEG and brain decodingBeyond Reconstruction: What EEG-to-Video Decoding Actually Recovers. Preprint 2025
- BloomCoresetOtherBloomCoreset: Fast Coreset Sampling using Bloom Filters for Fine-Grained Self-Supervised Learning. ICASSP 2025
20264 works
- Audio compositionGenerative visionWhy Multi-Source Audio Fails to Compose: A Geometric Diagnosis and Its Remedy. BMVC 2026
- CamTrol++Generative visionStabilizing Camera-Controlled Novel View Synthesis at Inference Time. arXiv 2026
- V-ASTARGenerative visionSynthesizing Compositional Videos from Text Description. WACV 2026
- Hierarchic-EEG2TextEEG and brain decodingHierarchic-EEG2Text: Assessing EEG-To-Text Decoding across Hierarchical Abstraction Levels. arXiv 2026
Papers
Conferences
-

Why Multi-Source Audio Fails to Compose: A Geometric Diagnosis and Its Remedy
BMVC 2026, Lancaster, UKAlso at the BMVC 2026 Doctoral Consortium
This paper explains why multi-source audio-to-image generation fails. Audio tokens sit in misaligned regions of CLIP space, so objects get ignored or merged. CLAP-based tokens and spatially separated cross-attention fix this and give faithful images of every sound source.
-
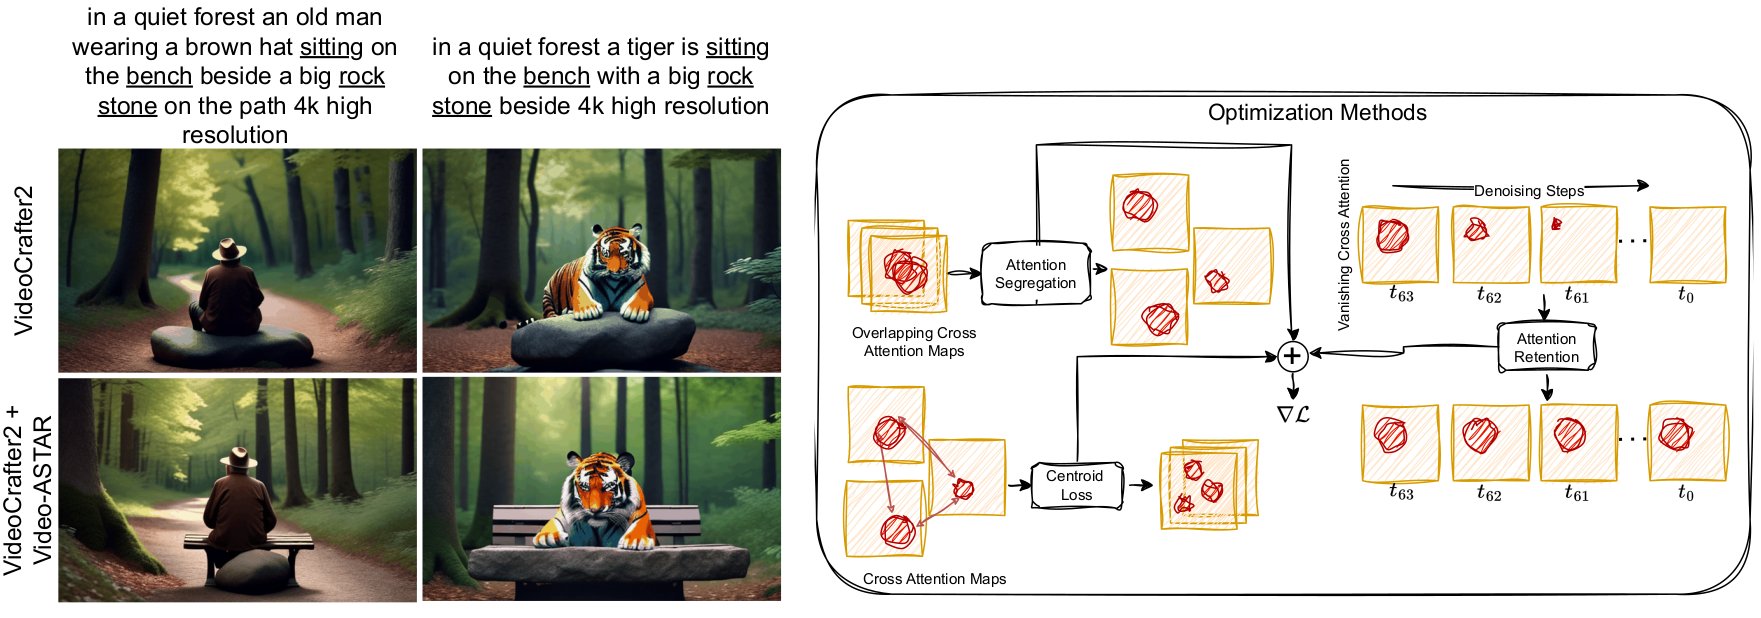
Synthesizing Compositional Videos from Text Description
WACV 2026, Tucson, AZ, USA
A training-free method for compositional video generation from a text prompt, built on a pre-trained video diffusion model. Video-ASTAR optimizes the cross-attention maps with a centroid loss and beats baselines in extensive experiments and ablations.
-
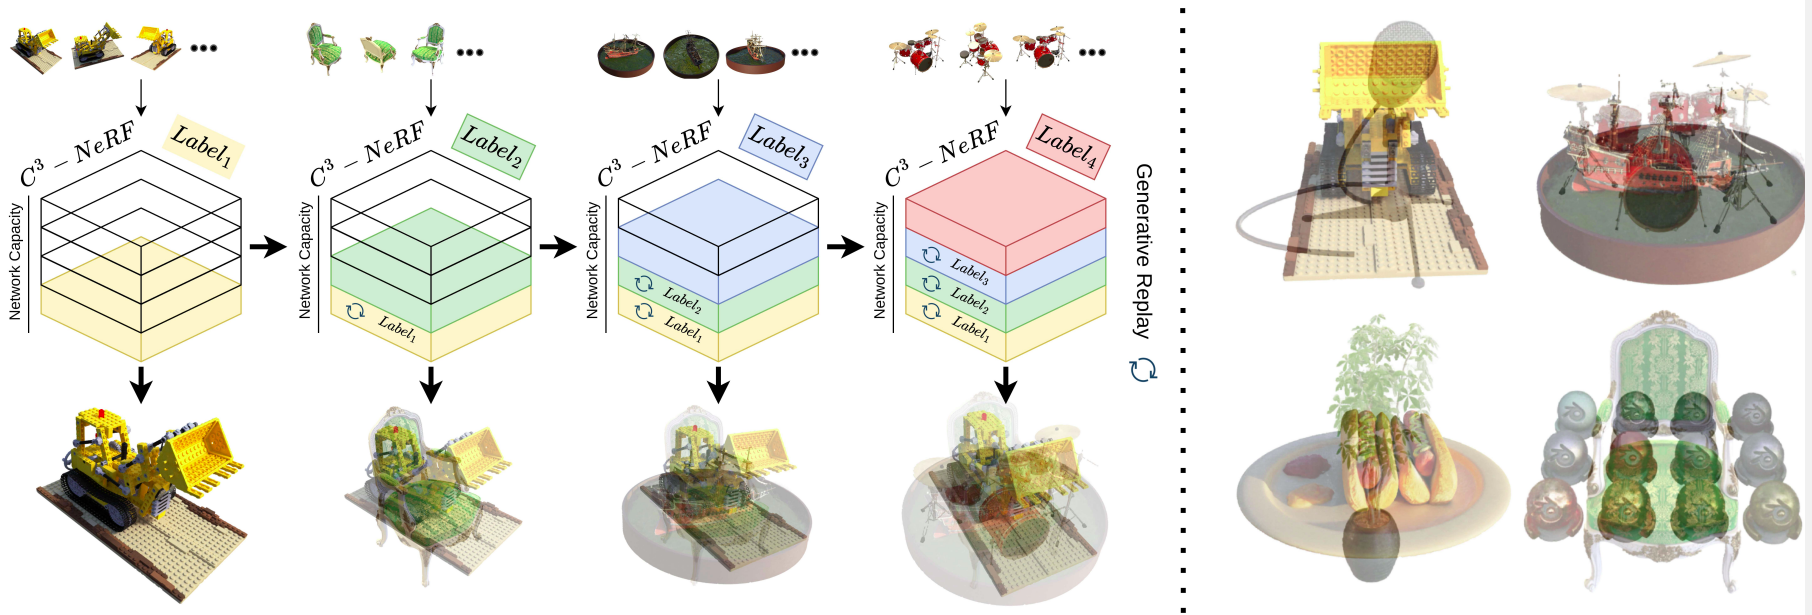
Incremental Multi-Scene Modeling via Continual Neural Graphics Primitives
BMVC 2025, Sheffield, UK
C-NGP encodes many 3D scenes in a single NeRF, conditioned on pseudo-scene labels. It learns continually with minimal forgetting and renders high quality novel views across scenes without adding parameters.
-
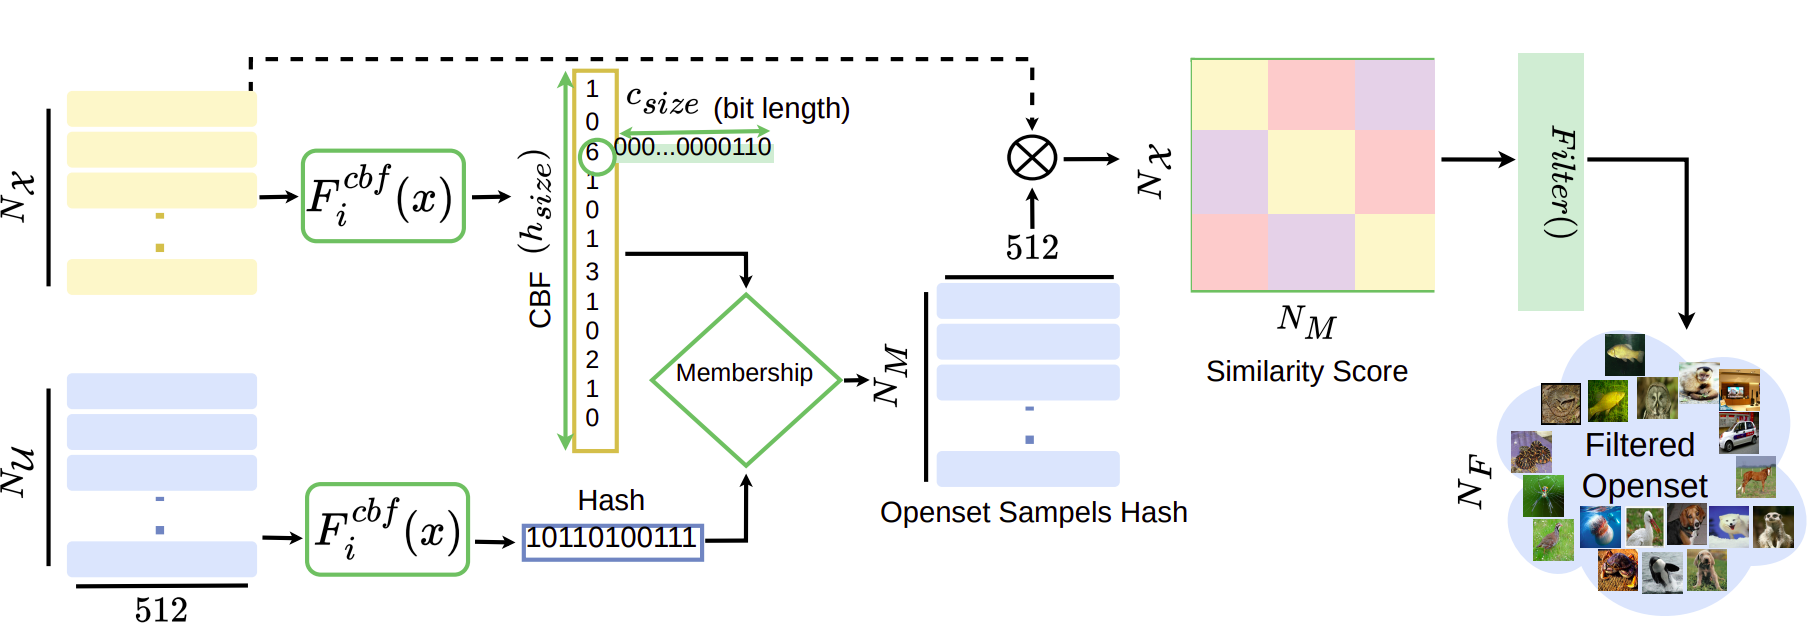
BloomCoreset: Fast Coreset Sampling using Bloom Filters for Fine-Grained Self-Supervised Learning
ICASSP 2025, Hyderabad, India
BloomCoreset stores and retrieves image features with Bloom filters for fine-grained self-supervised learning. It cuts sampling time from large unlabeled datasets by 98.5% at a 0.83% accuracy cost across 11 downstream tasks, and plugs into the SimCore framework.
-
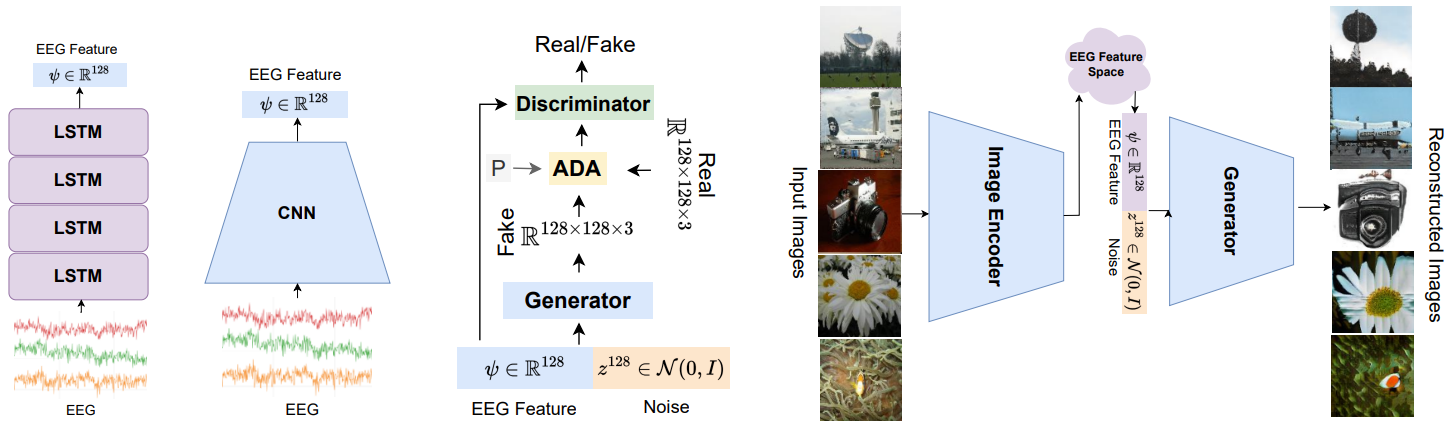
Learning Robust Deep Visual Representations from EEG Brain Recordings
WACV 2024, Waikoloa, Hawaii, USAFeatured in WACV DailyBest of WACV 2024
A two-stage method that learns deep visual representations from EEG features. It generalizes across datasets and outperforms GAN-based baselines on EEG-based image reconstruction and classification.
-
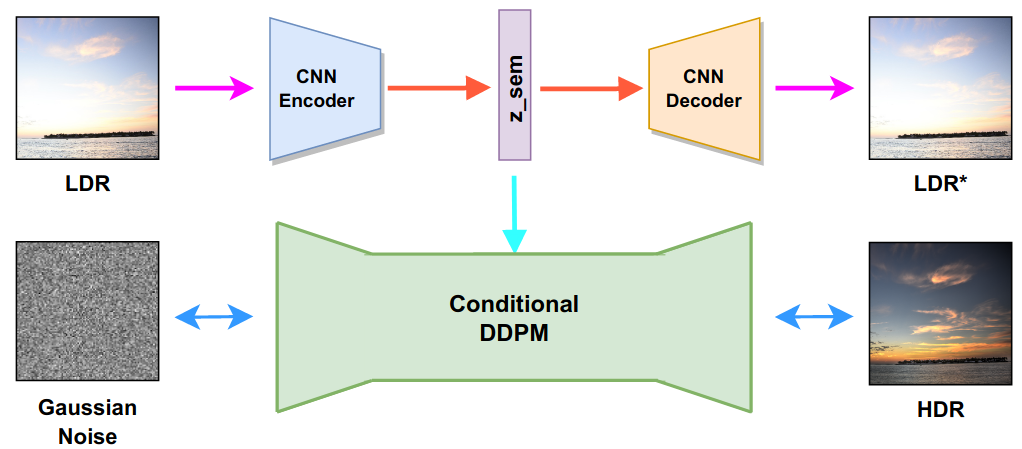
Single Image LDR to HDR Conversion using Conditional Diffusion
ICIP 2023, Kuala Lumpur, Malaysia
We cast single-image LDR to HDR conversion as image-to-image translation and solve it with a conditional diffusion model using classifier-free guidance. A CNN autoencoder improves the latent representation of the LDR image used for conditioning.
-
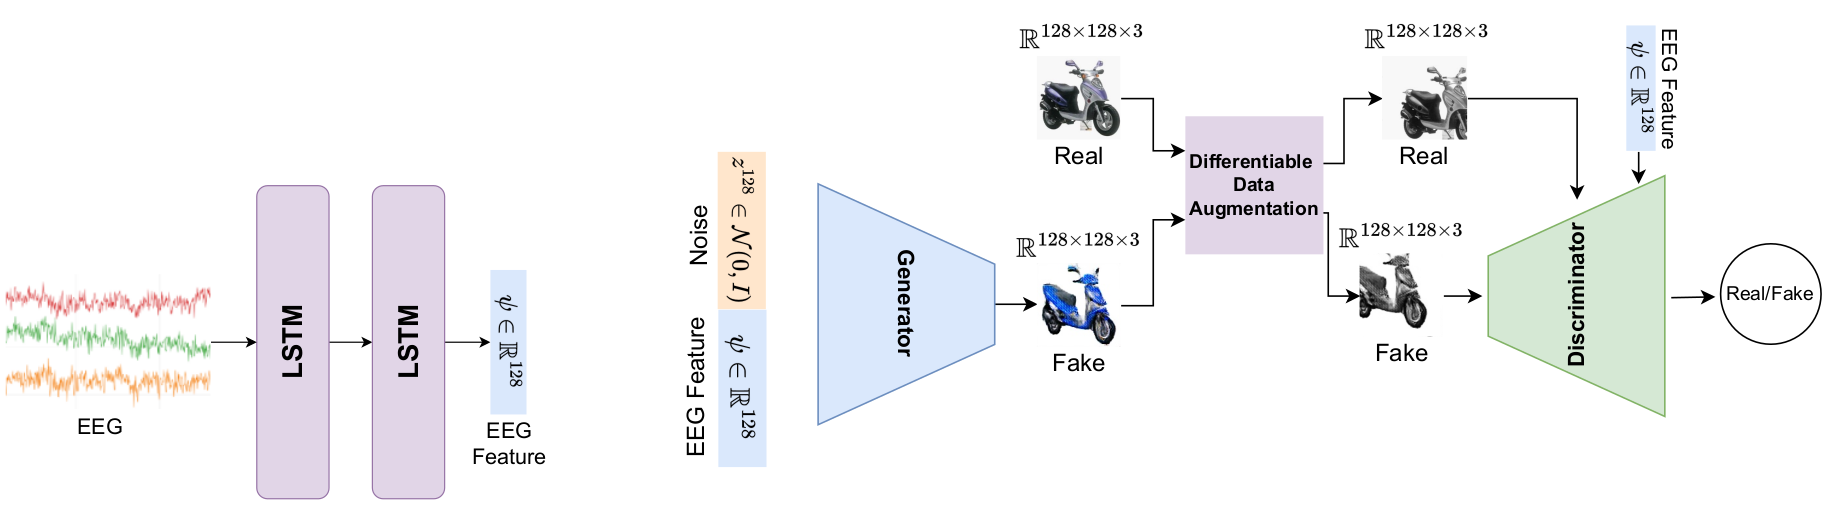
EEG2IMAGE: Image Reconstruction from EEG Brain Signals
ICASSP 2023, Rhodes Island, Greece
Contrastive learning extracts features from EEG signals, and a conditional GAN synthesizes images from them. A modified GAN loss lets the model produce 128x128 images from a small training set.
-
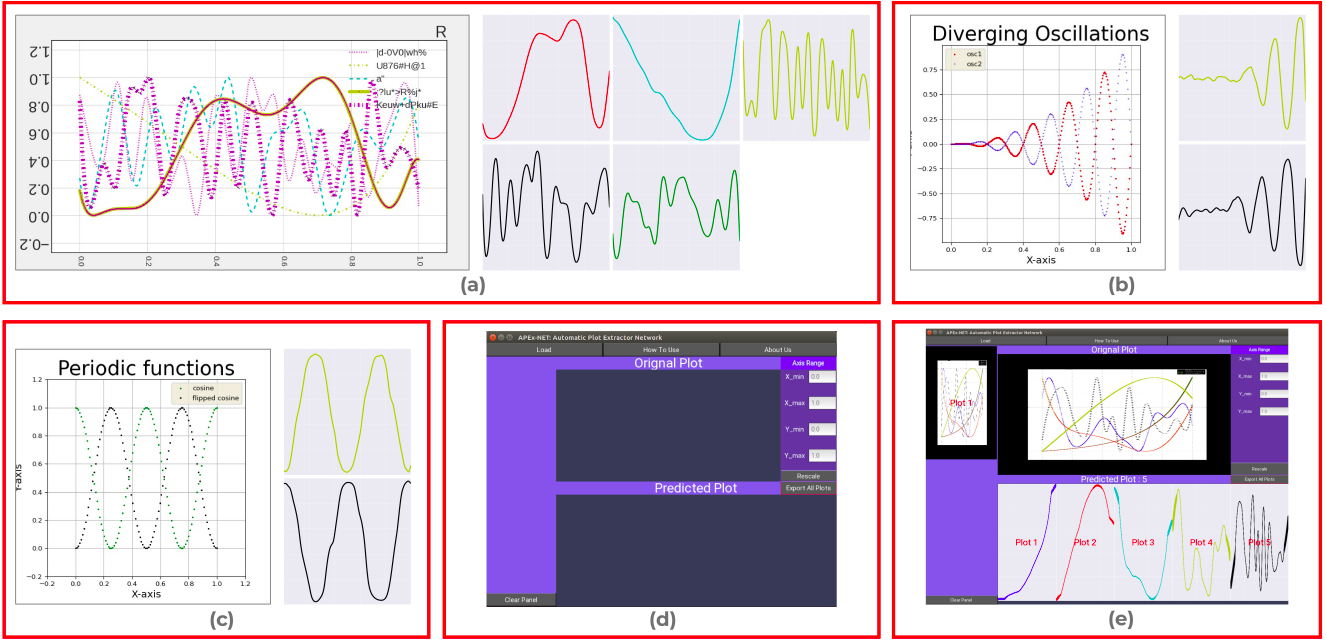
APEX-Net: Automatic Plot Extractor Network
NCC 2022, Mumbai, India
A deep learning framework with new loss functions that extracts data from plot images and cuts down manual effort. We also release APEX-1M, a large dataset of plot images paired with their raw data.
-
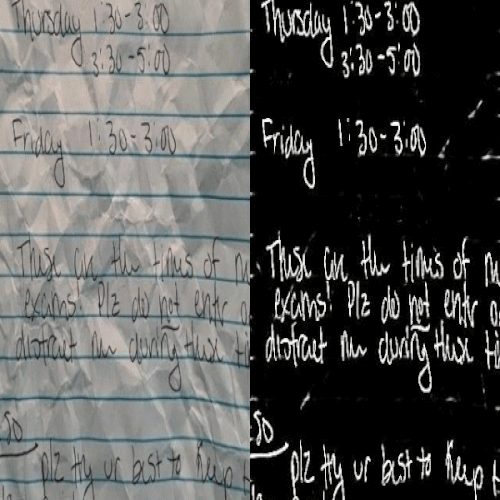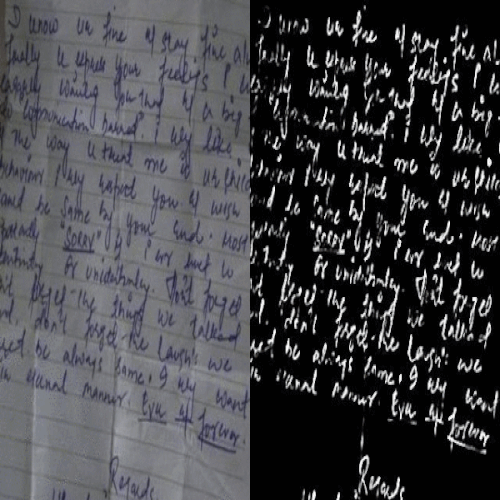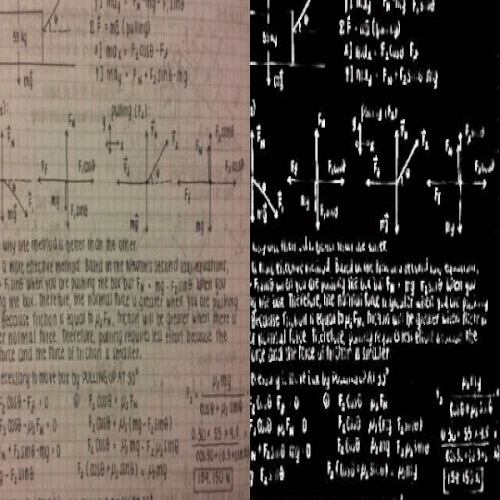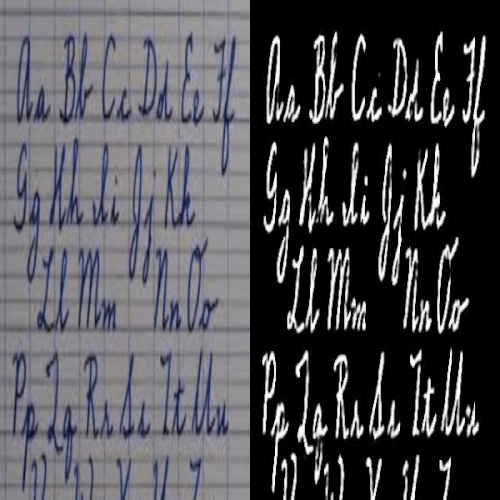
LS-HDIB: A Large Scale Handwritten Document Image Binarization Dataset
ICPR 2022, Montreal, Canada
A dataset of one million challenging handwritten document images with accurate segmentation ground truth, built for handwritten document image binarization.
Journal
-
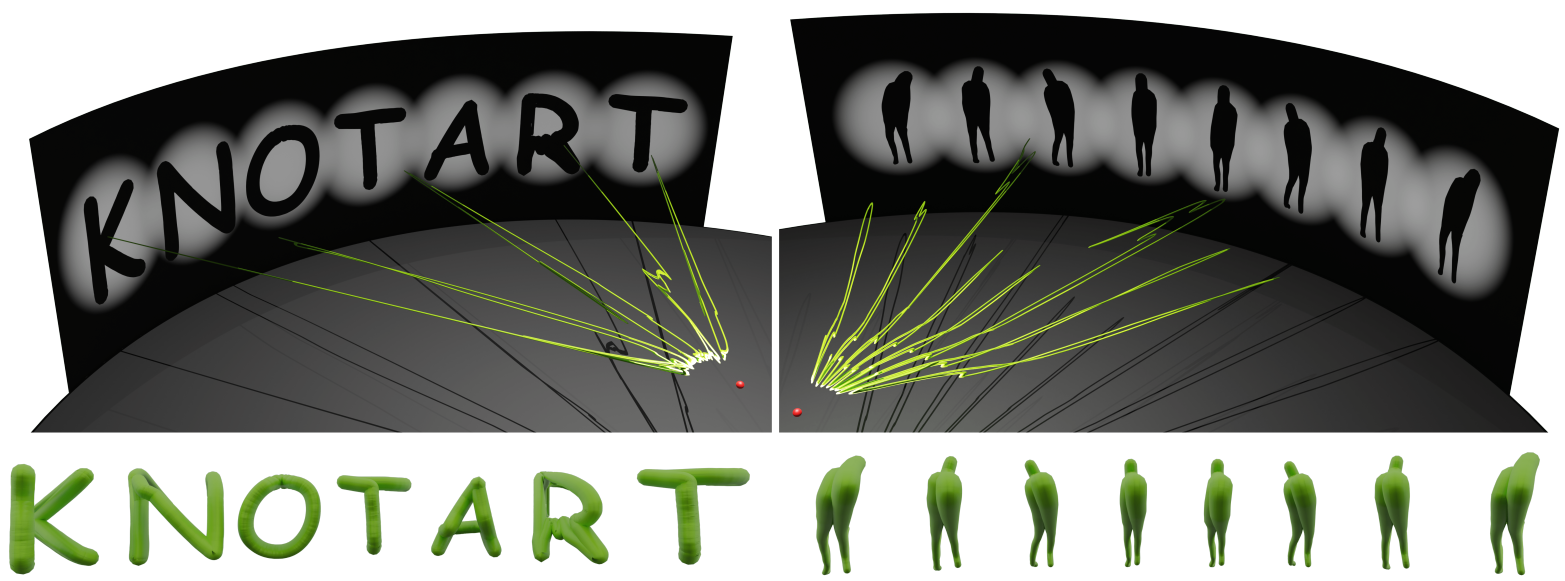
Search Me Knot, Render Me Knot: Embedding Search and Differentiable Rendering of Knots in 3D
Computer Graphics Forum 2024
A fully differentiable framework for designing 3D tubular knots that resemble a target image from chosen viewpoints. It pairs an invertible neural network with physically constrained optimization, validated by experiments, ablations and a 3D-printed object.
Posters and workshops
-
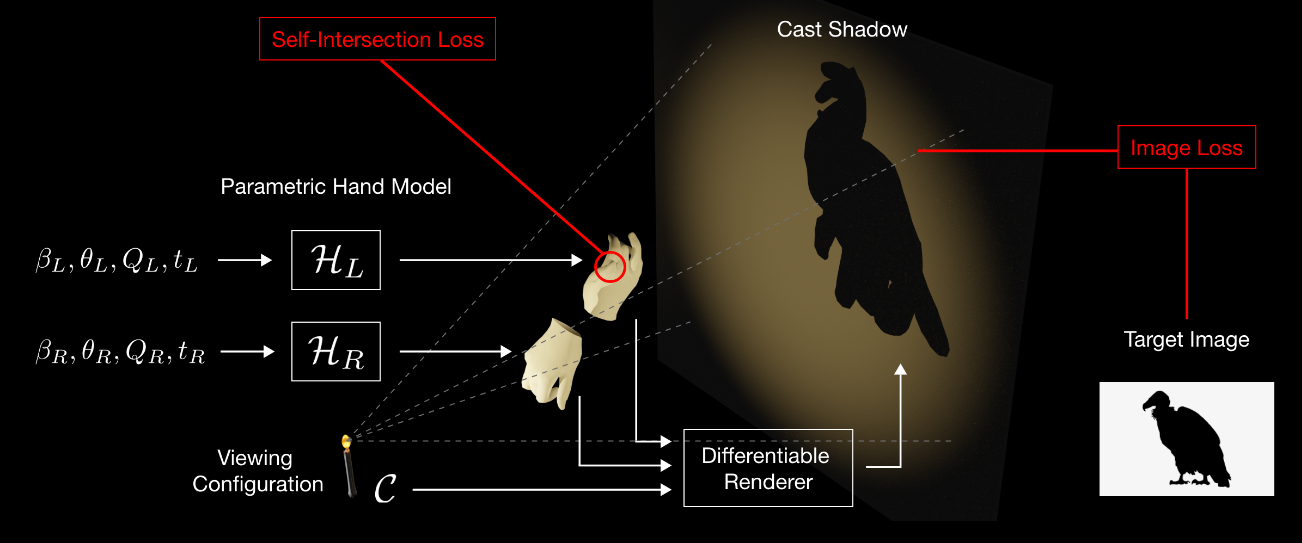
Hand Shadow Art: A Differentiable Rendering Perspective
Pacific Graphics 2023, Poster, Daejeon, KoreaBest Poster Award
Differentiable rendering deforms hand models so that the shadows they cast resemble a target image.
-
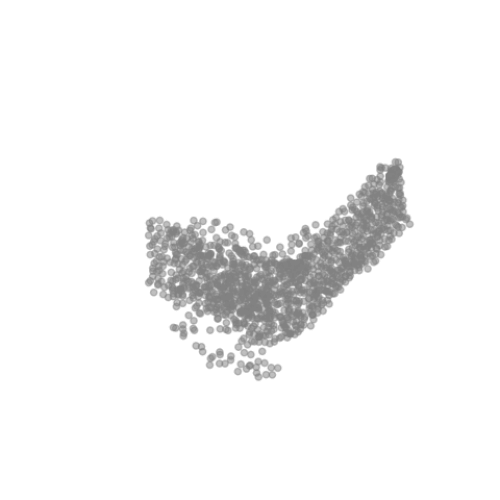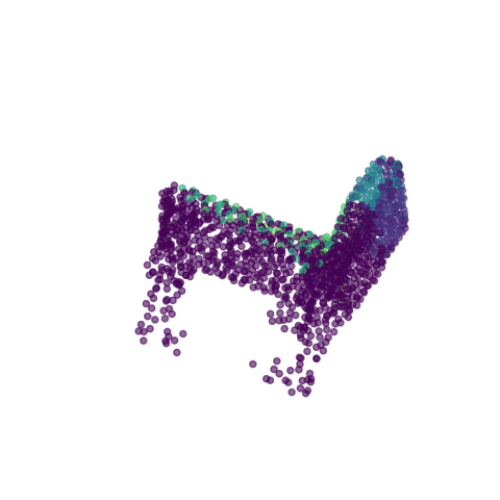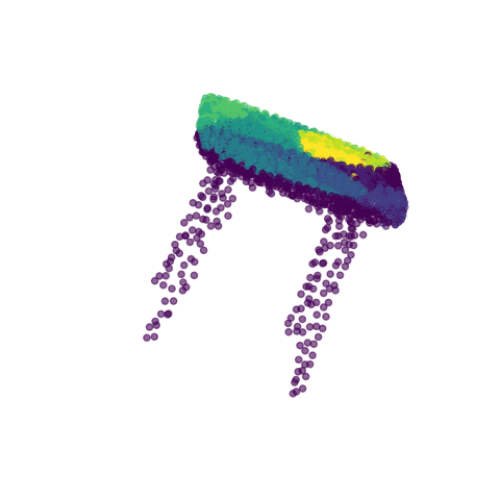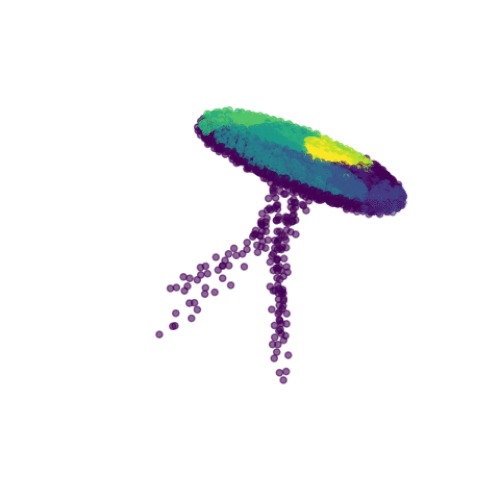
TreeGCN-ED: Encoding Point Cloud using a Tree-Structured Graph Network
Pacific Graphics 2023, Poster, Daejeon, Korea
A tree-structured autoencoder that builds robust point cloud embeddings from hierarchical information using graph convolution. Experiments and a t-SNE map show it separates object classes well.
-
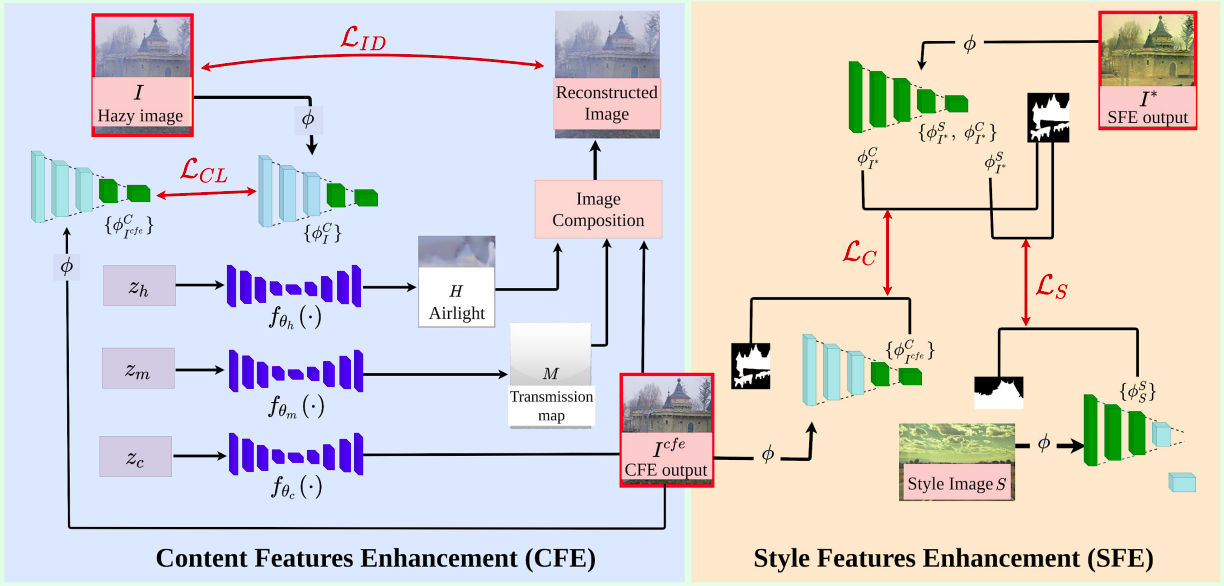
DILIE: Deep Internal Learning for Image Enhancement
WACV 2022, VAQ Workshop, Waikoloa, Hawaii, USA
Image enhancement with deep internal learning. DILIE improves content and style features while preserving the semantics of the enhanced image.
Preprints
-
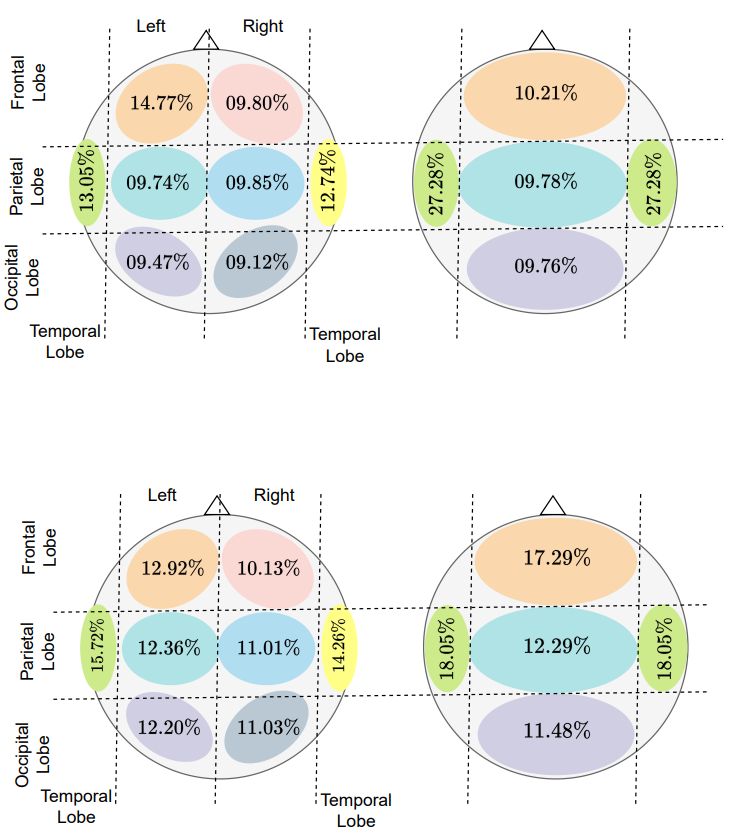
Beyond Reconstruction: What EEG-to-Video Decoding Actually Recovers
Preprint 2025
We study the dynamic visual information encoded in EEG and show that it can be reconstructed with temporally conditioned generative models. The work also asks what EEG-to-video decoding actually recovers of continuous visual experience.
Patents
Indian patent applications filed and published through IIT Gandhinagar.